Back to Work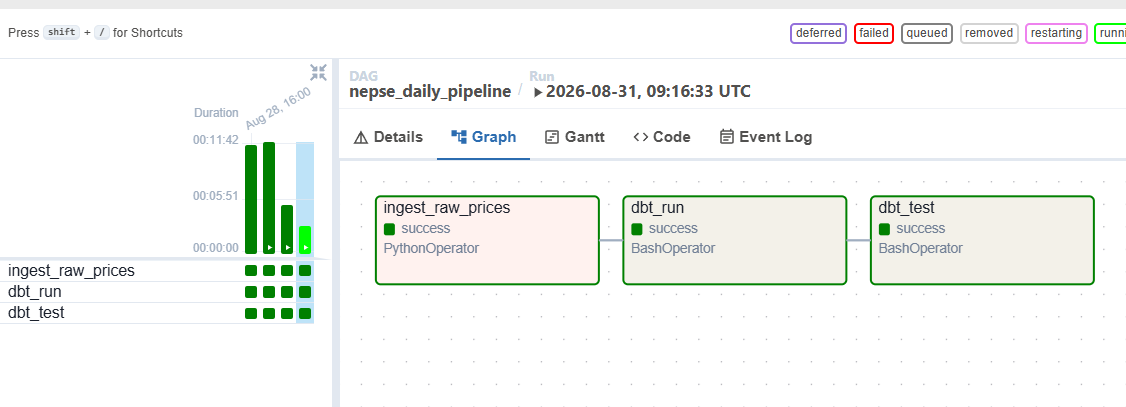
NEPSE Data Pipeline
An end-to-end data engineering pipeline that ingests daily stock price data from the Nepal Stock Exchange (NEPSE), transforms it into analysis-ready tables, and validates data quality automatically — every trading day, on a fully automated schedule with zero manual intervention.
Most portfolio projects use static Kaggle CSVs. This one uses live, real-world, locally-relevant data, and demonstrates the full lifecycle a data engineer is actually responsible for: ingestion, orchestration, transformation, testing, and observability.
Architecture: NEPSE API → Python ingestion → raw.daily_prices (Supabase Postgres) → dbt staging (stg_nepse_prices) → dbt marts (daily_returns, top_movers, moving_averages) → dbt tests (6 tests, all passing)
Orchestration runs on two intentional layers: Apache Airflow for local dev/demo of the task dependency graph and retry logic, and GitHub Actions as the lightweight production scheduler that actually runs the pipeline daily — same ingestion script, same dbt project, zero infrastructure cost.
Stack: Python, PostgreSQL (Supabase), Apache Airflow, dbt, dbt tests (dbt_utils + generic tests), GitHub Actions.
Data quality checks include not_null and unique-combination checks enforced across staging and all three mart models, accepted_values on mover_type, and a DB reconciliation check on every ingestion run comparing records scraped vs. records persisted.
Status: fully operational, running daily in production via GitHub Actions, with Airflow orchestration built and demoed locally.